


Eight weeks ago, Antonio Zarauz Moreno and I set out to build the Finetuning Course we wished had existed when we started.
Not another isolated tutorial, not a math-heavy paper walkthrough, not a "just run this notebook" guide with zero explanation.
We wanted something different: a structured, step-by-step journey that connects every piece — from understanding what pretraining actually does, all the way to deploying a finetuned model in production.
Theory on Wednesday, hands-on code on Friday, live discussion on Sunday.
Every week, for eight weeks.
And now… the journey is complete.
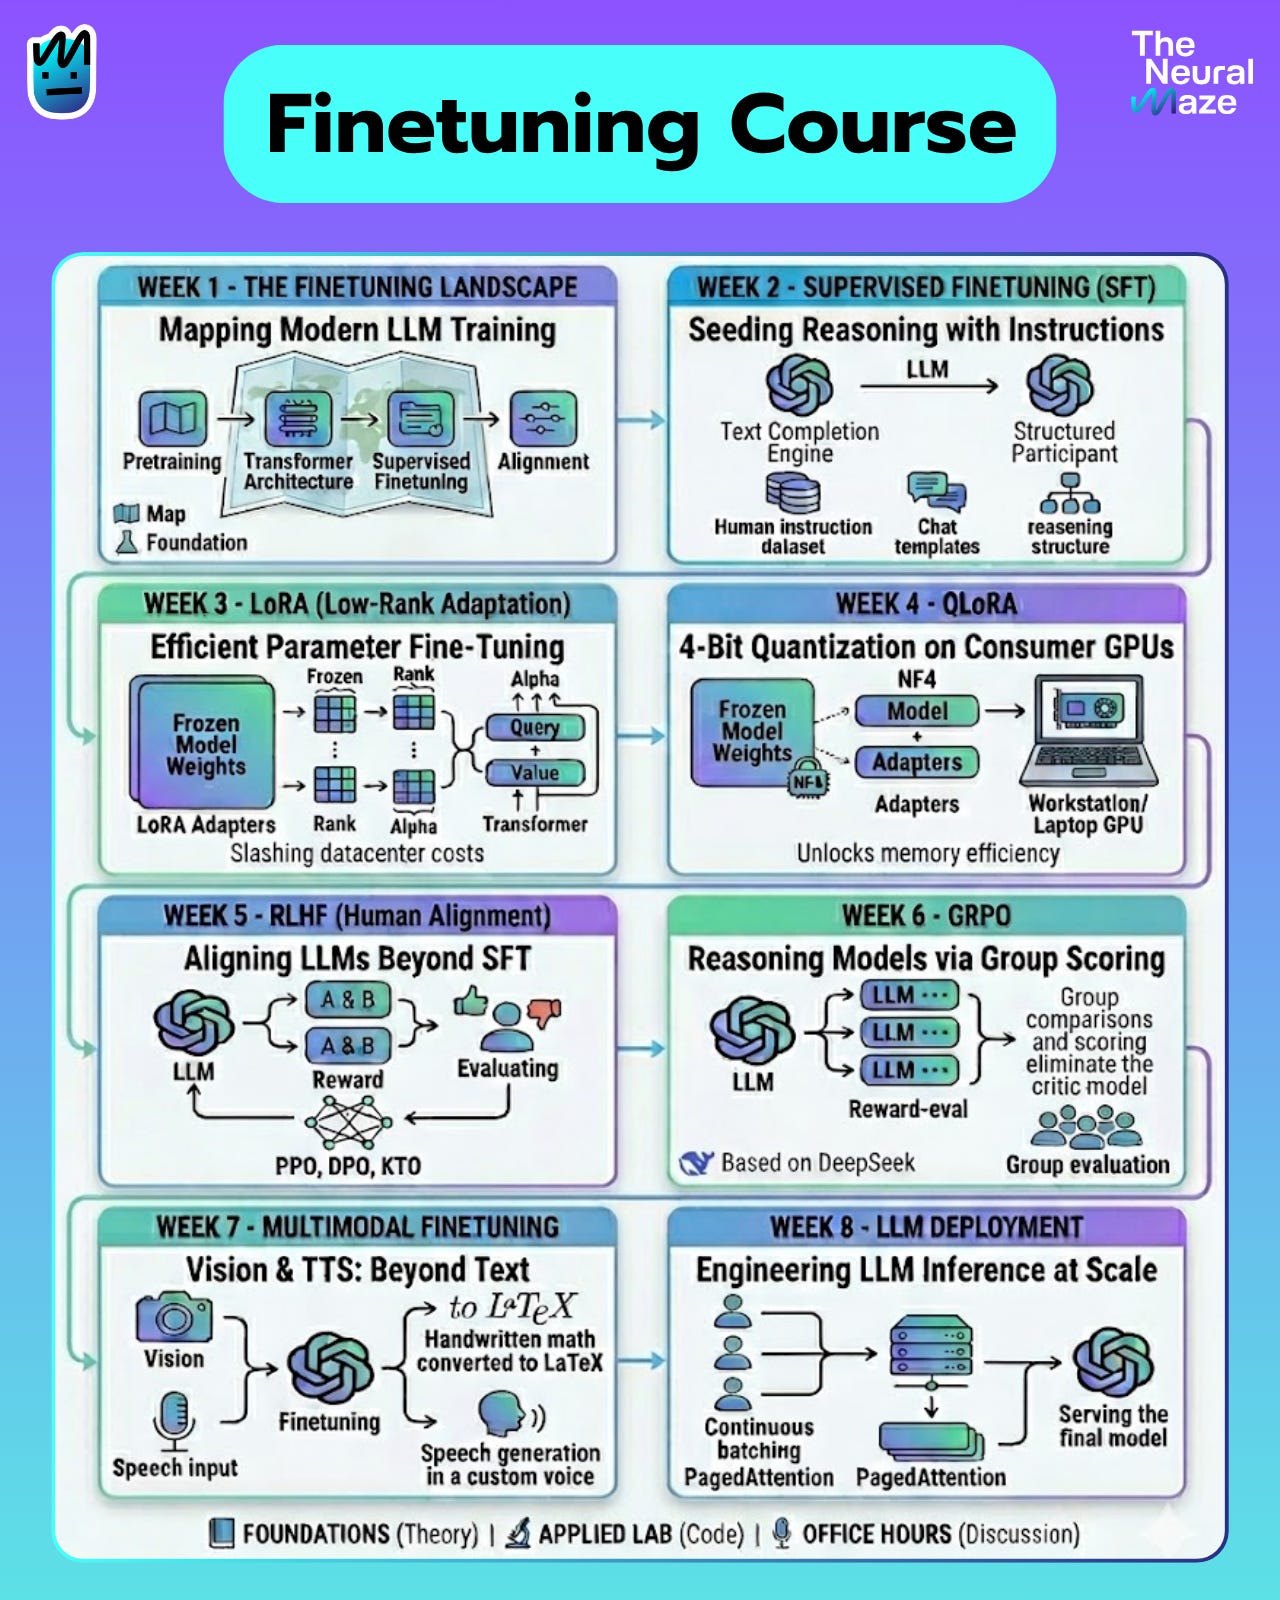
Whether you followed along from day one or you're discovering this today, every article, every lab, and every office hour recording is waiting for you.
The full course is right here, and you can start whenever you're ready.
🙋 Each lesson includes three types of content:
📘 Foundations Article → Conceptual grounding and mental models (Free)
🔬 Applied Lab → Hands-on implementation walkthroughs (Premium)
🎙️ Office Hours → Recorded live sessions with Q&A and deep dives (Premium)
Lesson 1 — The Finetuning Landscape
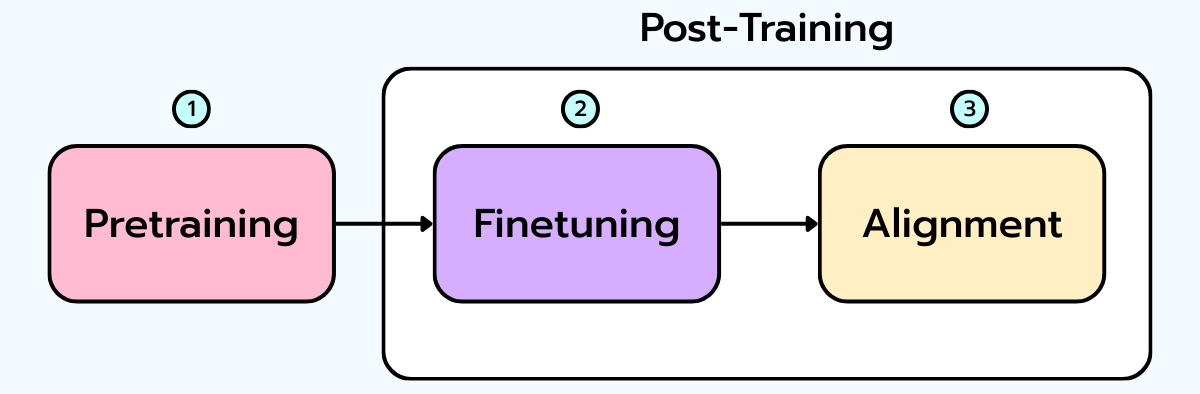
Before diving into any technique, you need the map. In this first lesson, we break down what pretraining really means, introduce the Transformer architecture, and walk through the full LLM training pipeline — from pretraining to supervised finetuning to alignment. Think of this as the foundation everything else builds on. Once it clicks, every lesson that follows makes more sense.
📘 The Finetuning Landscape — A Map of Modern LLM Training
Lesson 2 — Supervised Finetuning
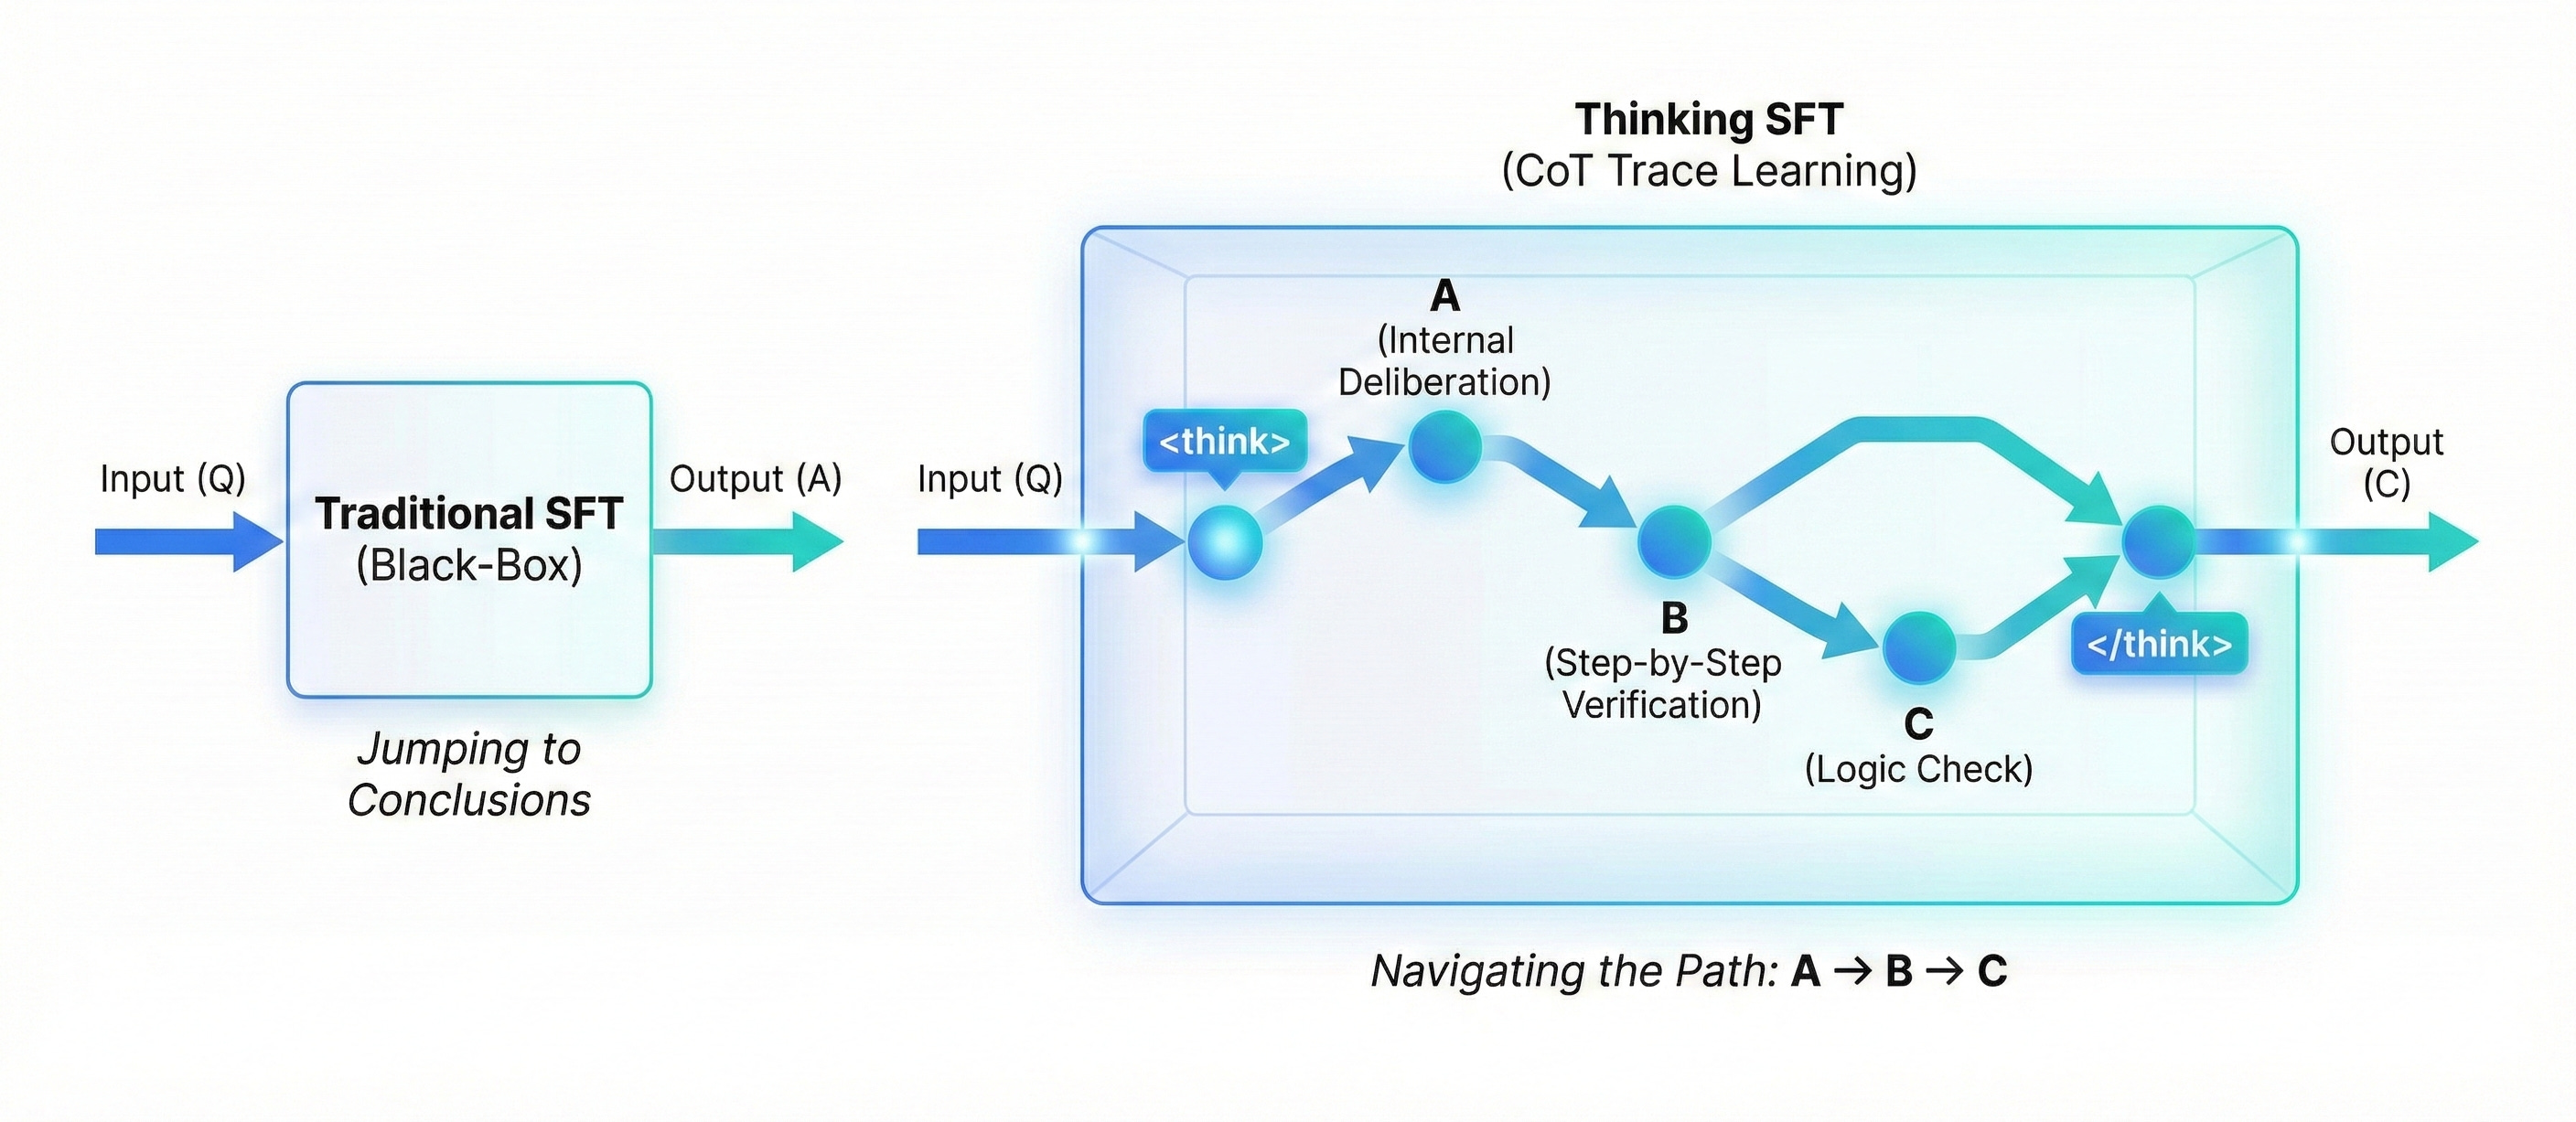
This is where a base model stops being a text completion engine and starts behaving like a participant. We cover SFT end to end: why it exists, how loss masking works, chat templates, instruction formats, dataset creation, and the difference between finetuning base models vs instruct models.
We also explore how SFT is the step that seeds reasoning into a model — the structure that makes everything downstream possible.
📘 The Engineer's Guide to Supervised Finetuning
🔬 Supervised Finetuning for Reasoning Models (From Dataset to Deployment)
Lesson 3 — LoRA

Full finetuning works, but it's expensive and often wasteful. LoRA changes the equation entirely. In this lesson, we build intuition for why low-rank adaptation works, explore where LoRA adapters fit inside the Transformer, and break down the hyperparameters that actually matter — rank, alpha, and target modules. The lab shows exactly how LoRA slashes memory from datacenter-scale to workstation-scale.
📘 Understanding LoRA from First Principles
Lesson 4 — QLoRA
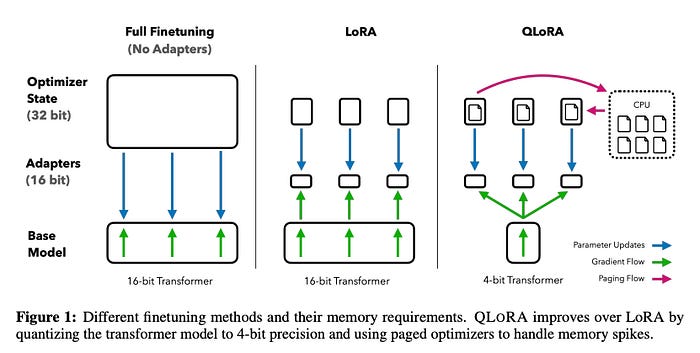
What if you could finetune a frontier model on a single consumer GPU? That's the promise of QLoRA. We walk through how 4-bit quantization works, why NF4 is purpose-built for neural network weights, and how a quantized base model cooperates with higher-precision LoRA adapters. By the end, you’ll know not just how QLoRA works, but when and why to reach for it.
📘 QLoRA Explained — How 4-Bit Quantization Unlocks Frontier Models
Lesson 5 — RLHF

SFT teaches a model how to respond. Alignment teaches it which responses humans actually prefer. In this lesson, we explore the RLHF landscape from the ground up: what reinforcement learning means in the context of language models, how reward models work, and the key algorithms — PPO, DPO, and KTO. The lab puts KTO into practice so you can see the difference alignment makes.
📘 The RLHF Landscape — Aligning LLMs Beyond SFT
Lesson 6 — GRPO
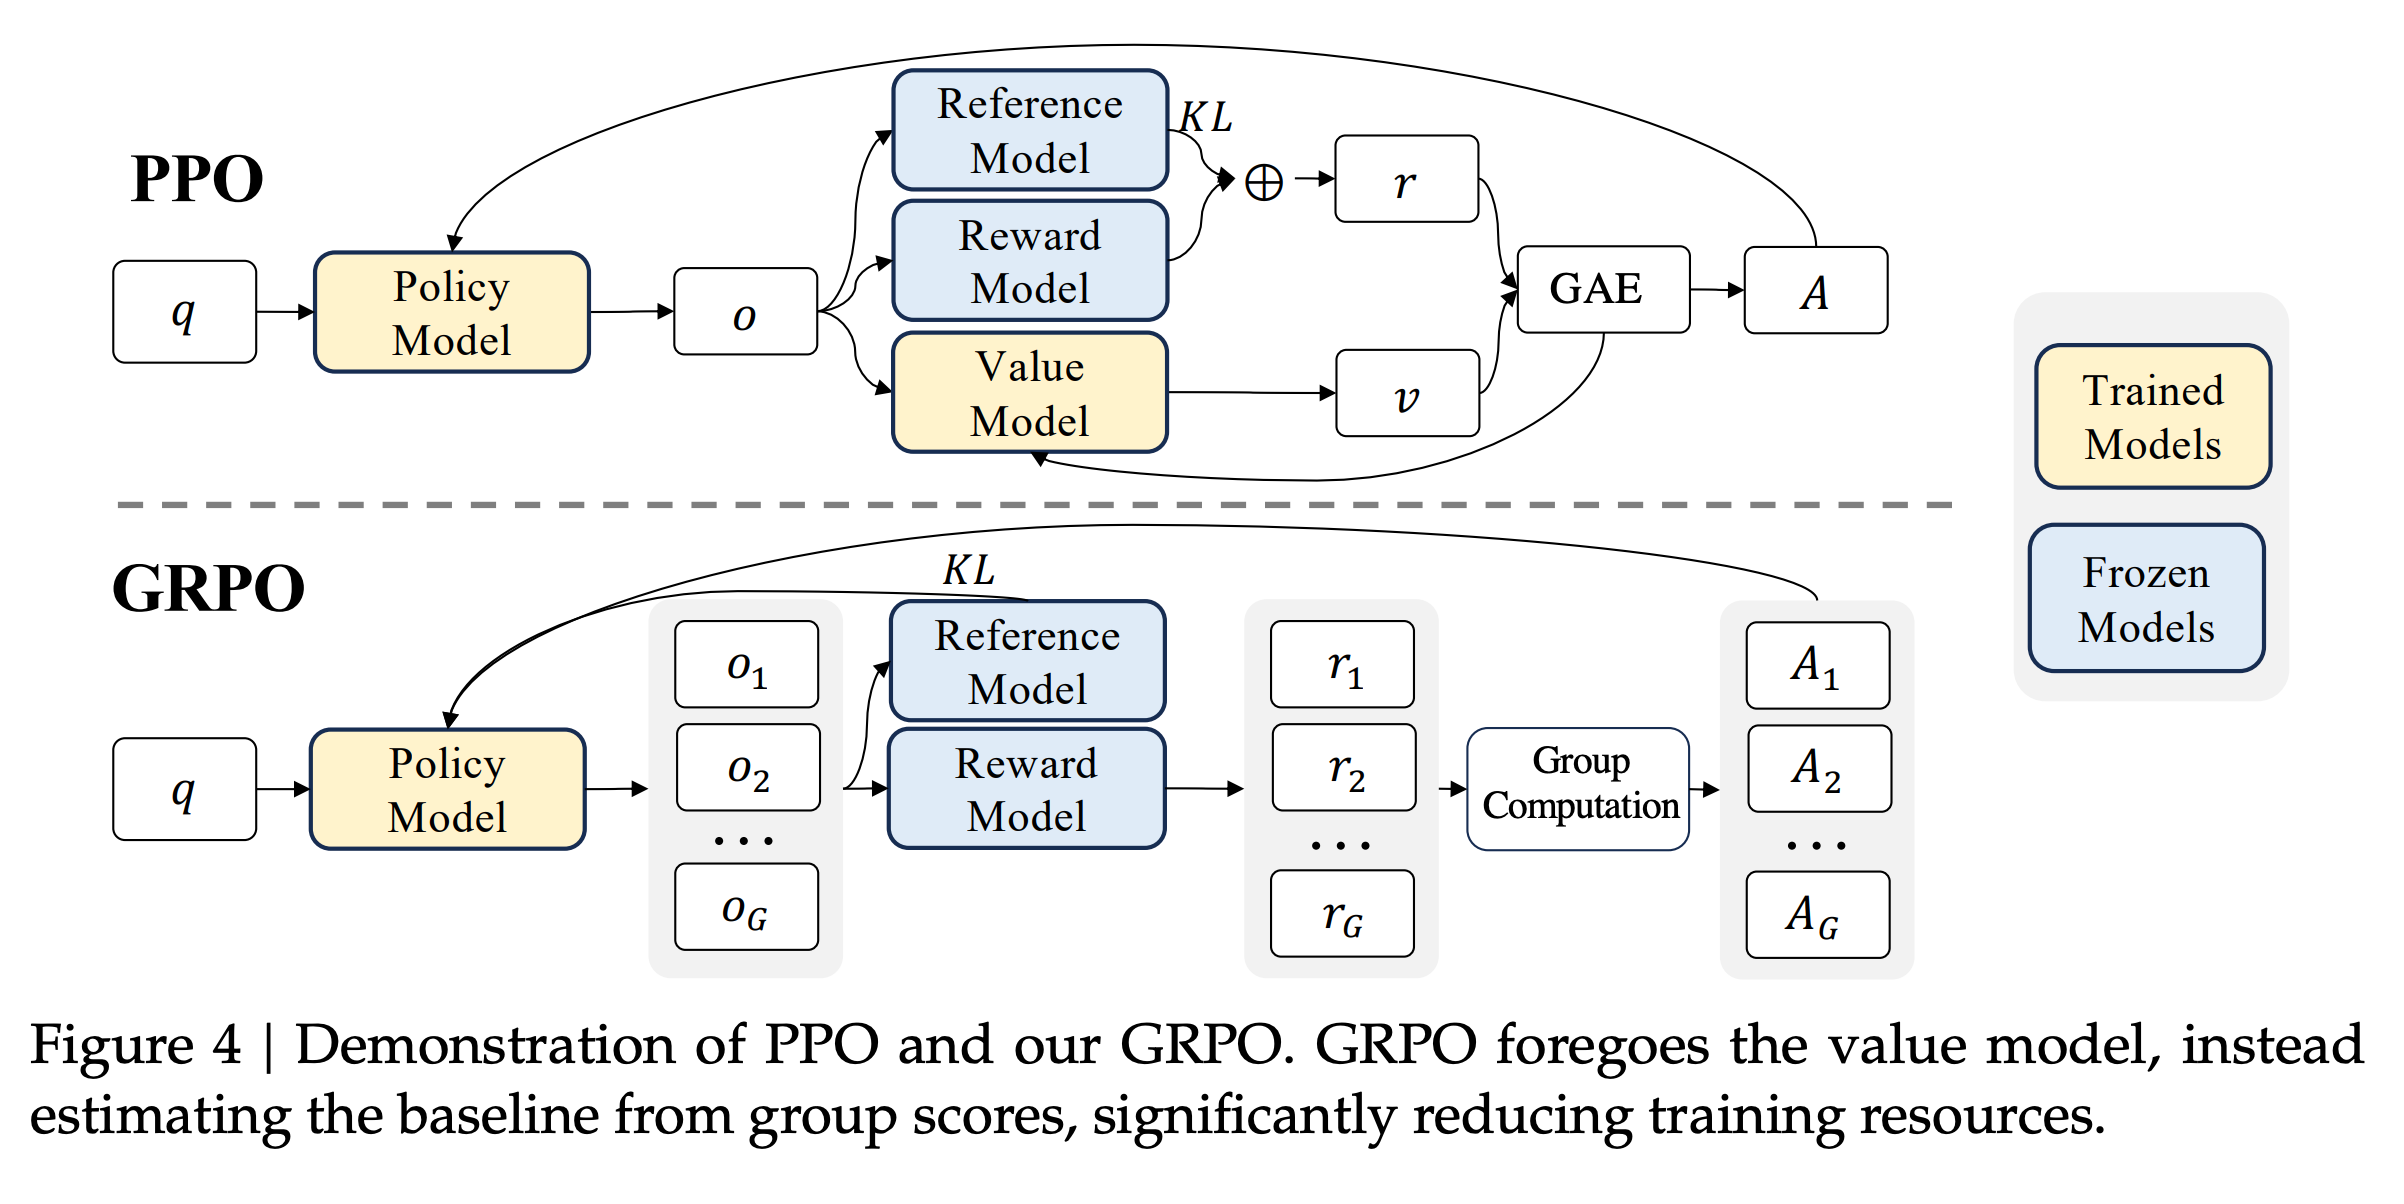
GRPO deserves its own lesson. Born from the ideas behind DeepSeek's reasoning models, it eliminates the critic model that makes PPO so expensive and replaces it with group-based scoring. We cover how GRPO works, why it matters for training reasoning models, and how it fits into the broader alignment landscape. The lab walks you through training a reasoning model on consumer hardware with GRPO and vLLM.
📘 The RL Algorithm Behind DeepSeek’s Reasoning Models
🔬 Training a Reasoning Model on Consumer Hardware with GRPO and vLLM
Lesson 7 — Multimodal Finetuning
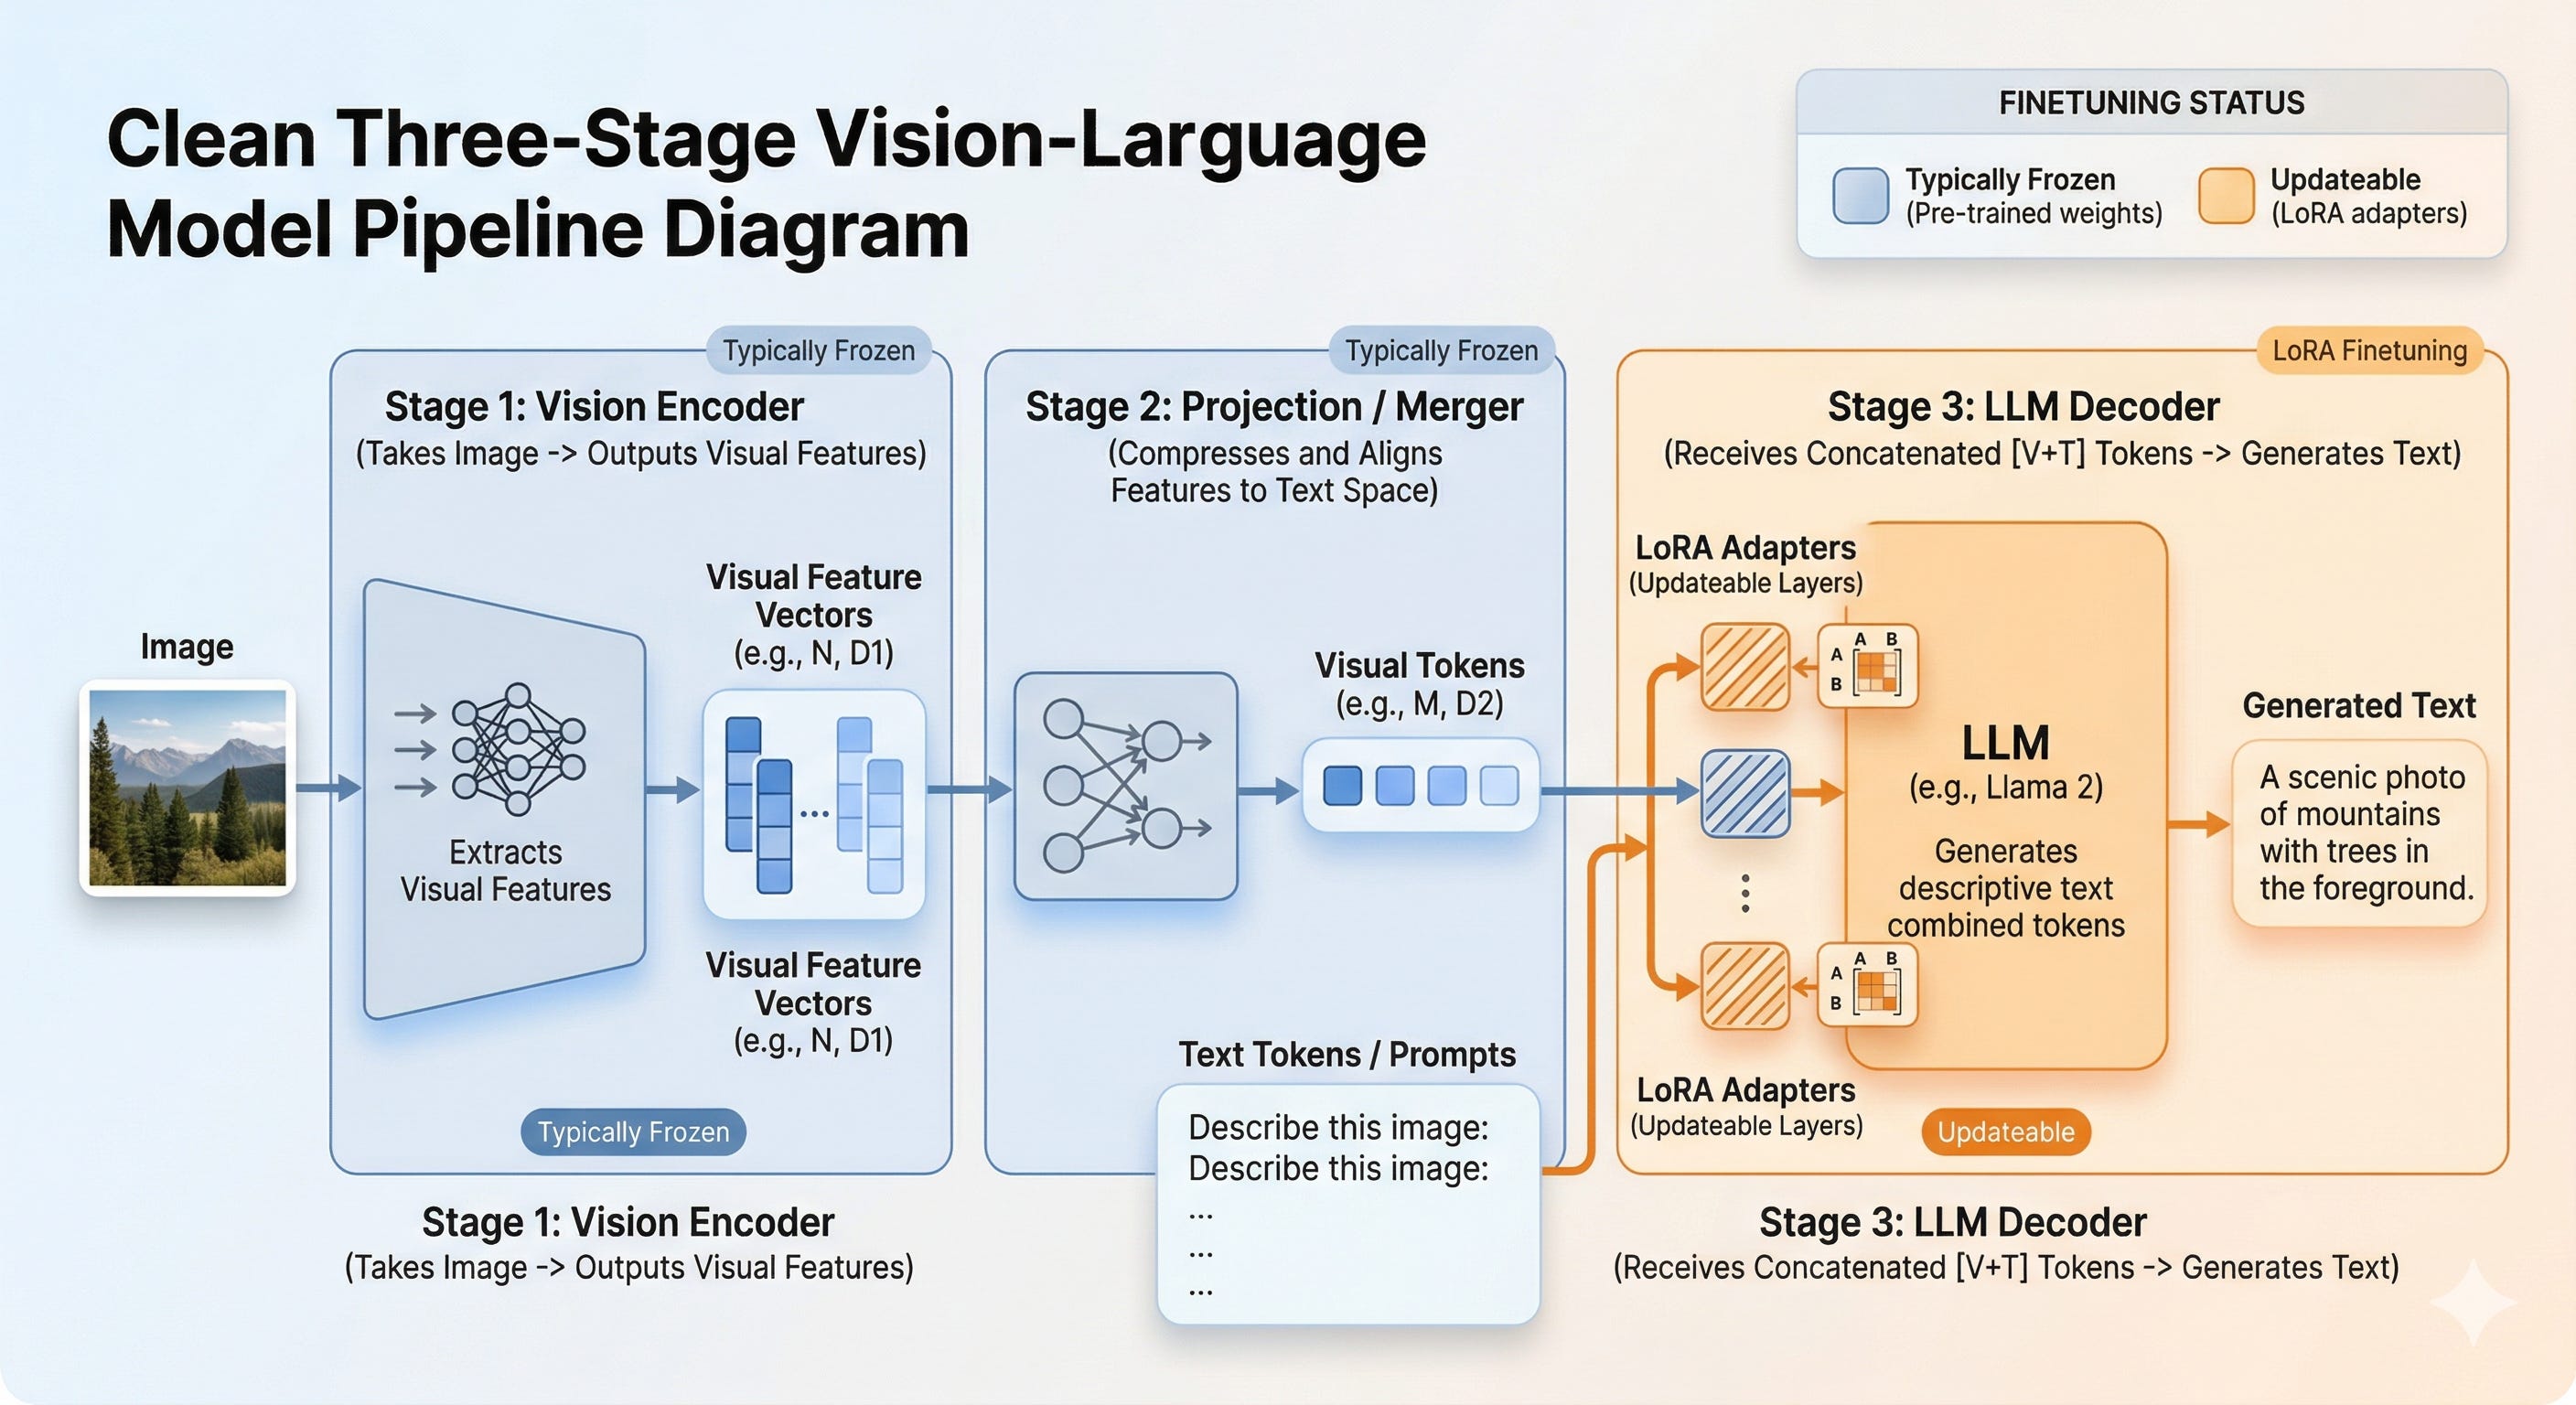
Everything you've learned so far — LoRA, QLoRA, SFT — applies almost identically to models that see images and generate speech. In this lesson, we go beyond text and explore vision finetuning (teaching a model to understand images) and TTS finetuning (teaching a model to speak with a custom voice). The lab is one of the most fun in the series: you'll finetune Qwen3-VL to convert handwritten math into LaTeX, and Orpheus 3B to generate speech in a custom voice — both on free Colab.
📘 Beyond Text: A Guide to Vision & TTS Finetuning
🔬 The Builder’s Guide to Multimodal Finetuning (Vision + TTS)
🎙️ Week 7 Office Hours → Cancelled
Lesson 8 — LLM Deployment
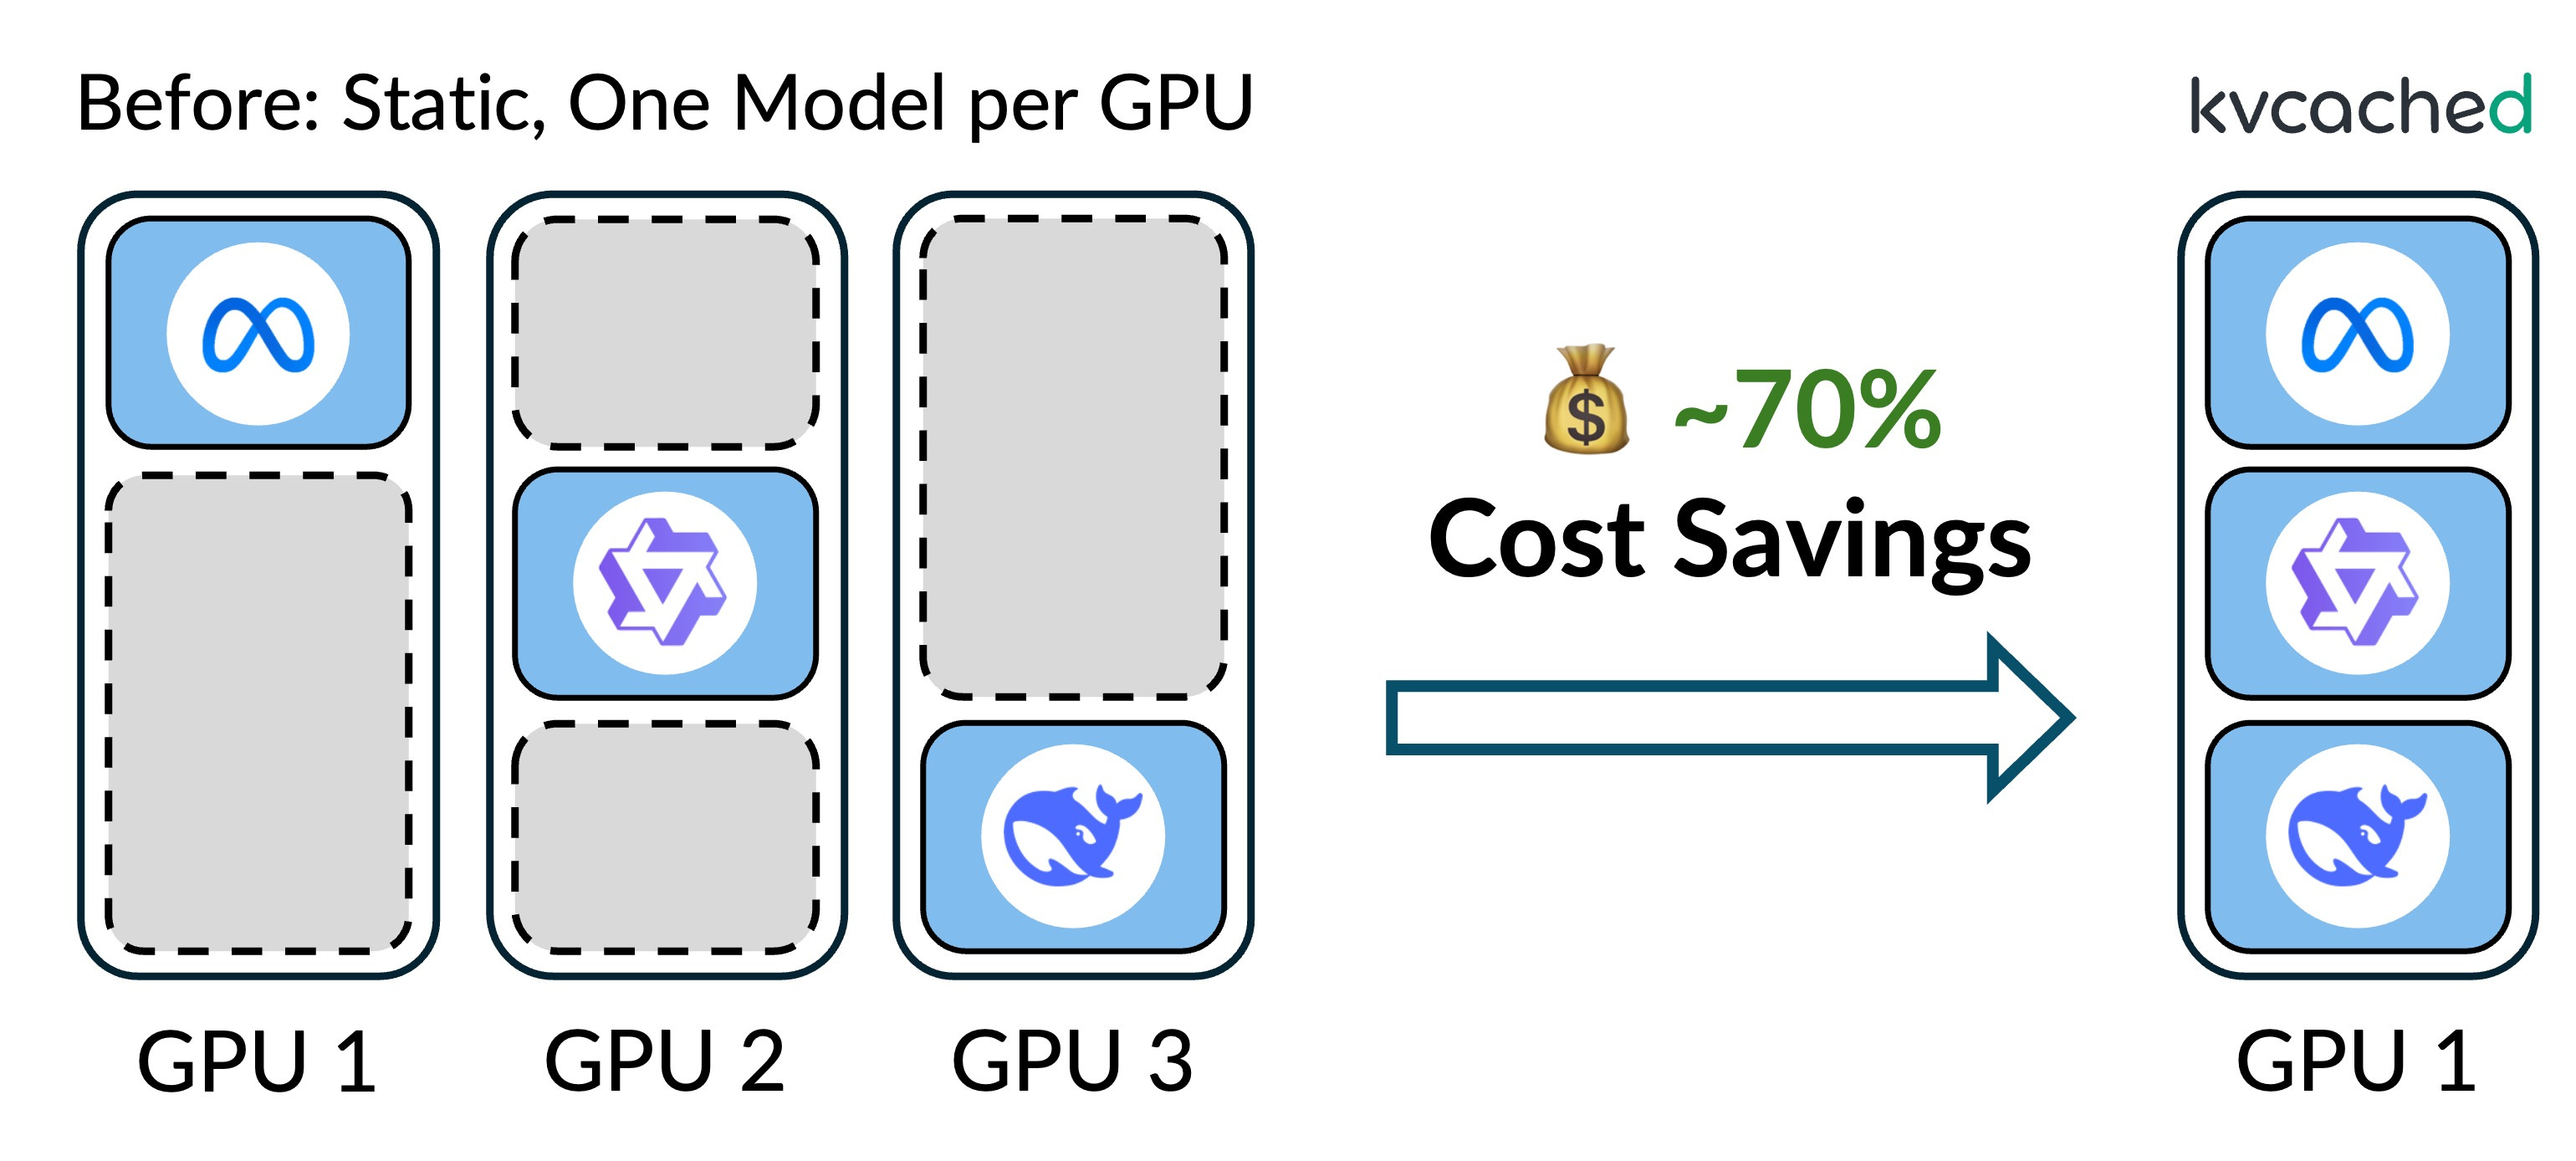
You've trained the model. Now serve it. In this final lesson, we tackle the engineering challenge of LLM inference at scale. We cover the two phases every request goes through (prefill and decode), why they fight over the same GPU, and the chain of ideas — continuous batching, PagedAttention, chunked prefill, prefill-decode disaggregation — that make production serving possible. The lab brings it all together with hands-on deployment.
📘 A Practical Guide to LLM Inference at Scale
Ready to start?
The entire course is here, waiting for you. A complete path from first principles to deployment.
If you're a free subscriber, you already have access to all eight foundations articles — start reading and see if the style clicks!
If you want the full experience — the labs where you actually build things, the office hours where we go deep — go Premium and unlock everything!
🦥 A huge thank you to Unsloth for sponsoring this course and making this content possible. If you've enjoyed the labs, you've already seen their tools in action!
Next Steps
We're already working on the next course. I won't spoil too much, but think deploying complex agent architectures to cloud providers and building real products out of them … end to end 😎
We have the structure mapped out, but there are a few areas where we'd love your input. Understanding your pain points helps us put our effort exactly where it matters most!
In the coming days, I'll be sending out a survey so you can vote on what you'd like us to cover.
✉️ Keep an eye on your inbox, your voice shapes what we build next!
Until next time, dear builder 👋